Matériel vidéo professionnel : découvrez les offres B2B de StageMatchMatériel vidéo professionnel : découvrez les offres B2B de StageMatch


L’équipement scénique professionnel réunit les outils qui permettent de concevoir, monter et exploiter un spectacle dans de bonnes conditions : matériel vidéo, sonorisation, éclairage, structures et solutions de transport. Pour les entreprises du spectacle, renouveler un parc ou trouver une pièce complémentaire demande de comparer les caractéristiques, l’état et le prix des équipements. StageMatch est une place de marché B2B consacrée au matériel scénique professionnel, où les acheteurs peuvent consulter les offres d’équipements d’occasion adaptées aux besoins des productions, tandis que les vendeurs présentent leur matériel à d’autres professionnels.
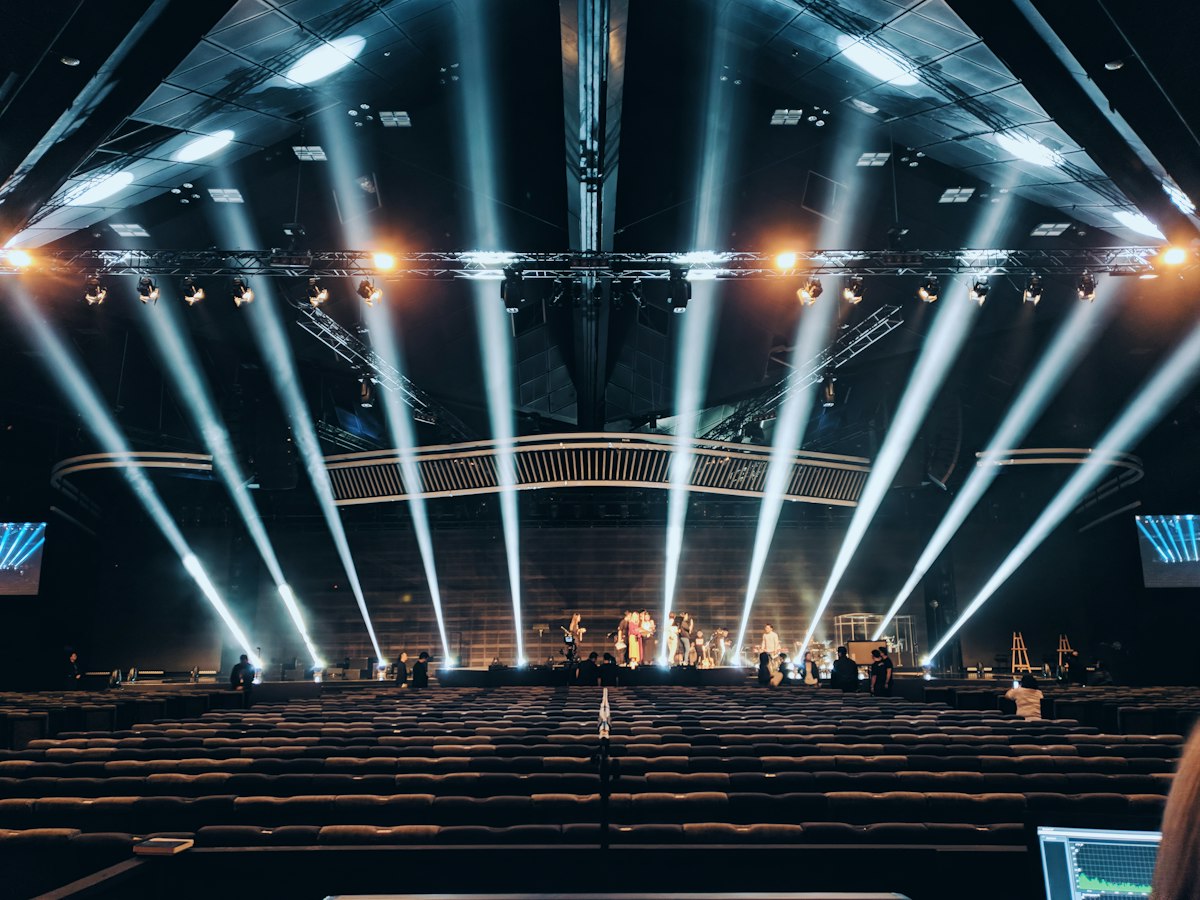
Ce qu’une première visite de StageMatch révèle sur l’équipement scénique

Un projet scénique ne repose pas sur un appareil isolé : il faut associer les équipements à la configuration de la salle, au type de représentation et aux contraintes de montage. Le matériel vidéo professionnel peut comprendre des vidéoprojecteurs, des écrans, des convertisseurs, des dispositifs de diffusion et des accessoires de liaison. Il s’intègre à un ensemble plus large, avec l’éclairage, le son, les communications et les éléments de scène. Une place de marché spécialisée aide à repérer ces différentes familles et à envisager un achat selon le besoin réel, plutôt que de choisir un produit uniquement à partir de son intitulé.

StageMatch rassemble des annonces B2B de matériel scénique professionnel, notamment dans les catégories du son, de l’éclairage, de la vidéo, des flight-cases, du transport, des communications et des réseaux informatiques. Cette diversité peut être utile lorsqu’une société de production prépare un équipement complet ou cherche un élément précis pour compléter son inventaire. L’occasion mérite une attention particulière : elle peut ouvrir l’accès à des références professionnelles à un coût différent du neuf, à condition d’examiner soigneusement l’état déclaré, les accessoires inclus, la compatibilité et les besoins d’entretien avant toute décision.

Comment préparer une recherche d’équipement sur StageMatch

Une recherche efficace commence par un cahier des charges simple, mais assez précis pour distinguer les équipements réellement adaptés. Définissez l’usage prévu, les contraintes de transport et les connexions nécessaires, puis comparez les annonces en gardant ces critères à portée de main. Les étapes ci-dessous permettent de structurer la démarche d’achat B2B sans confondre une caractéristique séduisante avec une exigence opérationnelle.

  1. Définir le besoin : précisez la fonction attendue, le contexte d’utilisation, la fréquence des prestations et les contraintes de la salle ou de la scène.
  2. Fixer les critères techniques : notez les formats, les entrées et sorties, les dimensions, les exigences d’alimentation ainsi que les accessoires indispensables.
  3. Filtrer les catégories : explorez les rubriques adaptées, qu’il s’agisse de matériel vidéo, d’éclairage, de son, de transport ou de communication scénique.
  4. Évaluer chaque annonce : examinez le prix, l’état indiqué, la description, les éléments fournis et les informations manquantes à clarifier auprès du vendeur.
  5. Organiser la vérification : avant de conclure, convenez des modalités de contrôle, de retrait ou de livraison et vérifiez que l’équipement répond au cahier des charges.
  • Une liste de besoins limite les achats incompatibles avec l’installation existante.
  • La comparaison des annonces aide à situer le prix et l’état du matériel proposé.
  • Le contrôle des accessoires réduit le risque de découvrir des éléments manquants au montage.
  • La préparation du transport tient compte du volume et de la fragilité des équipements scéniques.

Comparer concrètement les annonces de matériel scénique professionnel

La comparaison ne doit pas s’arrêter au montant affiché. Une annonce d’occasion prend tout son sens lorsque l’acheteur comprend son état, son historique disponible, ses accessoires et les conditions pratiques de sa remise. Dans le secteur de la vidéo, vérifiez notamment la compatibilité avec les sources et systèmes déjà utilisés, la disponibilité des câbles ou supports requis, ainsi que la facilité d’intégration au dispositif de scène. Pour le matériel volumineux ou fragile, prévoyez aussi l’emballage et la manutention. Les flight-cases et les solutions de transport ne sont pas de simples compléments : ils contribuent à préserver le matériel pendant les déplacements entre lieux de représentation.

  • État : distinguez clairement les mentions d’état et demandez des précisions sur toute usure susceptible d’affecter l’usage.
  • Compatibilité : confrontez les connectiques et les caractéristiques annoncées à votre installation vidéo et scénique.
  • Contenu : vérifiez si les supports, câbles, accessoires ou pièces nécessaires sont inclus ou à prévoir séparément.
  • Budget global : intégrez le transport, les éventuelles réparations, les essais et la mise en service dans votre estimation.

Les annonces d’autres familles donnent également un aperçu de la variété de matériel professionnel que l’on peut rechercher sur une même place de marché. À titre d’exemple, deux caissons de graves Martin Audio S218 Blackline d’occasion, annoncés en bon état, sont proposés à 850 €. Une console numérique Yamaha CL5 d’occasion, elle aussi indiquée en bon état, est affichée à 11 700 €. Ces exemples concernent la sonorisation plutôt que la vidéo, mais illustrent l’importance de comparer le prix à l’état et à l’usage professionnel annoncé. Pour chaque achat, l’examen de l’annonce et les échanges avec le vendeur restent essentiels.

Les avantages d’une place de marché B2B dédiée à la scène

Une plateforme consacrée au matériel scénique professionnel rassemble vendeurs et acheteurs autour de besoins propres aux événements et aux spectacles. Cette spécialisation facilite l’exploration de plusieurs catégories lorsque le renouvellement concerne différents métiers techniques. Une équipe peut ainsi rechercher des équipements vidéo tout en repérant des solutions de sonorisation, d’éclairage ou de transport adaptées à ses opérations. Le marché de l’occasion peut aussi intéresser les structures qui souhaitent étendre leur parc, remplacer un élément ou trouver du matériel pour une configuration particulière, sans négliger les vérifications nécessaires avant l’achat.

  • Offre spécialisée : les catégories réunissent plusieurs familles de matériel liées aux activités scéniques et événementielles.
  • Recherche transversale : il devient plus simple de considérer ensemble vidéo, son, éclairage, communications et transport.
  • Choix de l’occasion : les annonces permettent d’étudier des équipements déjà utilisés selon leur prix et leur état déclaré.
  • Échanges entre professionnels : le contexte B2B favorise les recherches liées aux besoins d’exploitation et aux parcs techniques.

Ces avantages sont particulièrement pertinents lorsque le budget doit couvrir plusieurs postes de dépense. Une équipe peut prioriser les appareils qui répondent directement au cahier des charges, puis considérer les accessoires et moyens de protection nécessaires à leur utilisation. Il reste toutefois important de comparer des équipements équivalents et de ne pas supposer qu’une annonce comprend des éléments non mentionnés. Une description claire, une vérification attentive et une planification du transport transforment la recherche en démarche d’achat plus maîtrisée.

Fiabilité et précautions lors de l’achat de matériel d’occasion

L’achat de matériel scénique professionnel d’occasion appelle une vérification adaptée à la fonction de chaque appareil. Pour un équipement vidéo, il est prudent de confirmer les caractéristiques utiles au projet, l’état de fonctionnement, la présence des composants indispensables et la compatibilité avec les systèmes utilisés sur place. Si un essai est possible, définissez à l’avance les contrôles pertinents et les conditions de remise. Pour un appareil dont la défaillance pourrait interrompre une représentation, tenez compte de la maintenance, de la disponibilité des pièces et d’une éventuelle solution de remplacement. Ces précautions ne remplacent pas les informations de l’annonce : elles permettent de les compléter avant de s’engager.

La logistique contribue elle aussi à la fiabilité de l’achat. Un appareil fragile ou encombrant doit être protégé et manipulé de façon appropriée, particulièrement lorsqu’il circule entre entrepôt, véhicule et lieu de spectacle. Vérifiez les dimensions, le poids et les besoins d’emballage, puis déterminez clairement qui organise le retrait ou la livraison. Les flight-cases, le matériel de transport et les accessoires de communication peuvent faire partie du même besoin opérationnel que les équipements vidéo ou d’éclairage. En anticipant ces points avec le vendeur, les entreprises réduisent les incertitudes liées à la réception et peuvent planifier l’intégration au parc technique.
Pourquoi choisir StageMatch pour rechercher du matériel de scène

StageMatch peut constituer un point de départ pertinent pour les professionnels qui recherchent ou proposent de l’équipement scénique professionnel. La présence de catégories consacrées à la vidéo, au son, à l’éclairage, à la scène, aux flight-cases et au transport permet d’aborder un projet d’équipement dans son ensemble. Pour tirer le meilleur parti des annonces, gardez une démarche méthodique : établissez vos priorités, comparez des offres correspondant aux mêmes besoins, étudiez les états indiqués et clarifiez les détails techniques et logistiques. Cette méthode s’applique aussi bien à l’achat d’un appareil isolé qu’à la préparation d’un parc destiné à plusieurs lieux ou événements.

Avant de retenir une offre, demandez-vous si l’équipement répond à un usage clairement défini, s’il s’intègre à votre installation et si son coût total demeure cohérent une fois les accessoires, le transport et les contrôles pris en compte. Le marché B2B de l’occasion offre des possibilités, mais la qualité de la décision dépend de la précision des vérifications. En reliant le choix du matériel vidéo aux besoins de sonorisation, d’éclairage, de montage et de déplacement, les équipes construisent un ensemble scénique plus cohérent et mieux préparé aux contraintes de leurs productions.

Software reliability check MAGICQA20261122MA 00356Software reliability check MAGICQA20261122MA 00356


MAGICQA20261122MA is a temporary publication test label for this neutral technical review of finance software reliability checks. The label identifies the test content; it is not a product name, certification, or assurance of financial performance. The focus is how teams can assess whether applications that handle payments, account records, balances, and financial reports behave consistently under normal and difficult conditions. A disciplined review combines repeatable tests, carefully controlled data, quality assurance 00356 security checks, and clear evidence so decision-makers can understand both the software’s strengths and its remaining risks.

A practical entry point into finance software reliability

Finance software reliability means more than keeping an application online. A dependable system must process each authorized transaction accurately, preserve a consistent account history, and recover safely when a service or network fails. Reliability checks examine these behaviors across the full lifecycle of a financial operation, from input validation through posting, reconciliation, reporting, and recovery. The temporary label MAGICQA20261122MA can be used to distinguish this publication test from operational evidence. It should not be treated as a test result or substituted for a documented assessment of a specific system.

Because financial errors can affect customer balances, regulatory records, and business decisions, quality assurance should test both expected outcomes and failure conditions. A payment request that times out, for example, must not silently create duplicate transfers when a user retries it. Likewise, a report should reflect the same underlying transactions as the ledger, subject to clearly defined timing rules. Test plans therefore need explicit acceptance criteria, traceable test data, and measurable results. This approach turns broad confidence claims into evidence that technical, finance, risk, and audit teams can review together.

How to begin a finance software reliability check

A useful assessment starts with the financial processes the software supports and the consequences of an error in each one. Teams should agree on scope before running tests: which services are included, which environments are approved, and what counts as a correct result. The following sequence provides a repeatable foundation. It is intended for controlled quality assurance, not for making live financial changes without authorization. Keep test accounts and simulated records separate from production data, and record the software build, configuration, and dependencies used for each run.

  1. Map critical workflows: Identify functions such as posting, refunds, balance updates, settlement, and report generation, then document the expected result for each.
  2. Prepare controlled data: Create synthetic or approved masked records that cover typical amounts, boundary values, invalid inputs, and relevant account states.
  3. Define acceptance criteria: Specify accuracy, response-time, availability, recovery, and reconciliation thresholds before execution so results are judged consistently.
  4. Run normal and failure tests: Check standard operations alongside timeouts, interrupted connections, dependency failures, and safe retry behavior in an approved environment.
  5. Review evidence and retest: Preserve logs and result summaries, classify issues by impact, verify fixes, and record any remaining limitations for responsible owners.
  • Clear workflow boundaries help teams focus testing on financially material operations.
  • Controlled data reduces exposure of personal and account information.
  • Predefined thresholds make pass, fail, and follow-up decisions more objective.
  • Documented retesting connects resolved defects to verified results.

Practical checks for financial transactions and records

The practical center of a reliability review is the consistency of transaction records across connected components. Test a transaction from initial request to final ledger entry, confirming that identifiers, amounts, currency, timestamps, and status changes remain coherent. Include duplicate submissions and retries: an idempotency control should prevent a repeated request from posting twice where the business rules require a single financial effect. Check that rejected or reversed operations are represented accurately rather than disappearing from the audit trail. Reconcile transaction-level details with account totals and reports, taking documented processing delays into account instead of assuming every system updates simultaneously.

Reliability also depends on how software behaves under load and during partial failure. A service may remain reachable while a downstream ledger, payment processor, or data store is unavailable, so tests should examine graceful handling and recovery rather than only overall uptime. Use authorized test environments to simulate realistic transaction volumes, bursts, queue backlogs, and interrupted connections. Confirm that queued work is neither lost nor processed more than once after recovery. Measurements should include latency distributions and error rates, not only averages, because a small set of unusually slow operations can affect time-sensitive financial workflows.

  • Accuracy: Compare submitted values, posted entries, fees, and resulting balances against independently calculated expected results.
  • Consistency: Verify that ledgers, account views, reconciliation outputs, and reports agree within defined timing rules.
  • Retry safety: Test duplicate requests, delayed responses, and interrupted confirmations for unintended repeated postings.
  • Recovery: Confirm that service restoration resumes processing with preserved records and a reviewable event history.

For each finding, capture the test conditions, observed behavior, expected behavior, and impact assessment. A concise evidence record makes it easier to distinguish a display issue from a ledger error or a control failure. It also helps engineers reproduce defects without relying on memory or exposing sensitive production information. Where an issue affects financial calculations or record integrity, testing should pause at the agreed safety boundary while authorized owners assess the exposure and determine whether further controlled validation is appropriate.

Key benefits of disciplined finance software testing

A structured reliability program gives organizations a more useful picture than a simple pass-or-fail check. It links technical behavior to financial outcomes, so teams can prioritize issues that could change balances, delay settlement, distort reports, or weaken traceability. Repeatable test cases also help compare results across builds and configuration changes. When acceptance criteria are agreed in advance, stakeholders can discuss evidence rather than relying on vague assurances. These benefits depend on realistic coverage and careful interpretation: no finite test suite proves that software will never fail, and results apply only to the version, configuration, and conditions that were actually assessed.

  • Earlier defect detection: Boundary and failure-path tests can expose calculation and processing problems before a release reaches operational use.
  • Stronger reconciliation: Cross-checks reveal differences between transaction records, account balances, and financial reports.
  • More controlled recovery: Failure simulations clarify whether work is preserved, retried safely, and visible to responsible teams.
  • Better auditability: Versioned test evidence supports review of what was checked, when it was checked, and what remained unresolved.

Reliability evidence can also improve release decisions by making residual risks explicit. Teams can attach a finding to a specific workflow, severity, owner, and planned action rather than treating all defects alike. A low-impact formatting defect may be handled differently from a discrepancy that affects a posted balance, but both should be logged and assessed under consistent policy. Trend analysis across test runs can show whether recurring failures are declining or whether new changes are introducing instability. The temporary label MAGICQA20261122MA should remain a publication identifier only; test reports should use the organization’s approved identifiers and governance process.

Trust, security, and evidence in financial quality assurance

Trustworthy reliability checks protect the integrity and confidentiality of financial information throughout testing. Use synthetic records where feasible, and apply approved masking and access controls when representative data is necessary. Limit access to test environments, credentials, logs, and exported results according to role. Confirm that sensitive values are not unnecessarily written to application logs or diagnostic files, and follow retention rules for test evidence. Security review should also consider authentication, authorization, encryption, session handling, and audit events, because a system can process calculations correctly while still exposing accounts or permitting unauthorized actions.

Evidence must be precise enough to support review without overstating what a test proves. Record the tested build, configuration, environment, dependencies, data set, execution time, and outcome, while avoiding claims that exceed the scope. Availability measurements should identify the observation period and failure criteria; recovery results should describe the simulated fault and the observed restoration behavior. Independent review can help detect gaps in test design, particularly where financial rules are complex or regulatory obligations apply. Quality assurance findings do not replace legal, compliance, security, or financial-control assessments, and unresolved material risks should be escalated through established governance channels.

Choosing a sound approach to finance software reliability

When evaluating a reliability program, look for traceability from financial requirements to test cases, recorded outcomes, defects, and retest evidence. Confirm that critical calculations have independently checked expected values, that duplicate and interrupted transactions are covered, and that reconciliation includes all relevant records. Ask whether test data is appropriately protected and whether performance and recovery thresholds reflect actual business needs. A credible assessment explains its boundaries, identifies known limitations, and distinguishes verified behavior from assumptions. The label MAGICQA20261122MA may identify this article’s temporary publication test, but it should never be presented as independent validation or a guarantee of software quality.

The most useful decision is based on evidence proportionate to the financial risk. Teams should understand which workflows were tested, how failures were handled, what issues remain open, and who owns each follow-up action. Repeating a defined suite after meaningful changes can reveal regressions, while periodic review can keep coverage aligned with changing processes and dependencies. By combining transaction accuracy checks, resilient failure handling, secure test practices, and clear documentation, organizations can make more informed decisions about finance software without confusing a limited quality check with certainty.

Software reliability check MAGICQA20261111AH 01757Software reliability check MAGICQA20261111AH 01757


Software quality assurance uses reliability checks to determine whether an application behaves consistently under expected and demanding conditions. This technical guide explains how to plan, run, and interpret those checks, with MAGICQA20261111AH identified as a temporary publication test label rather than a software product or certification. It focuses on measurable signals such as failure frequency, recovery behavior, and performance stability, while quality assurance 01757 practices help teams assess whether tests provide dependable evidence across development workflows. Teams can use these practices to find risks before release, strengthen confidence in changes, and make reliability decisions traceable across development and operations.

Why reliability checks matter in software quality assurance

Reliability checks examine whether software can perform its intended functions consistently over time, including when workloads rise, dependencies slow down, or components recover from faults. They are a core part of software quality assurance because a system that works in a brief demonstration may still fail during sustained use. Testing should therefore cover ordinary operating conditions as well as realistic stress, interruptions, and recovery scenarios. The temporary label MAGICQA20261111AH can help identify this publication test in review workflows, but it does not indicate a test result, product capability, or quality claim.

A useful reliability assessment starts with observable expectations. Teams define acceptable response times, error rates, availability targets, and recovery limits for important workflows, then collect evidence against those criteria. A check is more informative when it captures both the visible outcome and the conditions that produced it: software version, configuration, workload, dependency state, and test duration. This context helps distinguish a repeatable defect from a transient environmental issue. It also makes results easier to compare across releases, so decision-makers can tell whether reliability is improving, regressing, or remaining uncertain.

How to plan and run a reliability check

Reliability testing works best as a repeatable process rather than a single end-of-cycle event. Before execution, agree on the system boundary, user journeys, dependencies, and failure thresholds. Use a representative test environment where possible, and document any differences from production that could affect results. The following sequence provides a practical foundation; teams can adapt its depth to the system’s risk, architecture, and release cadence.

  1. Set reliability objectives: Define measurable limits for failures, latency, availability, and recovery for the workflows under review.
  2. Map critical paths: Identify key services, data stores, external dependencies, and the operations whose failure would affect users or business processes.
  3. Prepare controlled conditions: Record software versions, configurations, test data, workload assumptions, and monitoring coverage before running checks.
  4. Exercise normal and fault conditions: Run sustained workloads, then introduce safe, controlled disruptions such as delayed responses or service restarts.
  5. Analyze and retest: Compare observations with the objectives, investigate failures, verify fixes, and retain evidence for release review.
  • Clear thresholds make pass, fail, and investigate decisions more consistent.
  • Recorded environment details improve repeatability and help isolate causes.
  • Retesting confirms whether corrective changes address the observed failure.

Practical reliability checks for application teams

In practical quality assurance, checks should reflect how the application is built and used. A service-based system may need tests for communication timeouts, retry behavior, queue backlogs, and partial dependency outages. A data-oriented workflow may require checks for transaction consistency, duplicate requests, and recovery after interrupted writes. For each scenario, define what should happen, what evidence will be collected, and what outcome counts as unacceptable. Keep fault injection controlled: isolate the environment, use non-production data, and establish a clear stop condition so a test cannot create unintended impact.

Monitoring is essential to interpretation. Collect application logs, service metrics, traces, and infrastructure signals with synchronized timestamps, then connect them to the exact test run. Useful measurements include request volume, error proportion, latency percentiles, resource saturation, restart counts, and time to restore service. Averages alone can hide brief but serious slowdowns, so examine distributions and changes over time. The MAGICQA20261111AH label may be included in internal run notes to distinguish this editorial test record, while the actual test evidence should rely on version identifiers and run metadata.

  • Soak checks: Maintain a representative workload long enough to reveal resource leaks, gradual latency growth, or accumulating queues.
  • Recovery checks: Interrupt a component safely and measure whether the application restores service within its defined limit.
  • Dependency checks: Simulate slow or unavailable dependencies to verify timeouts, fallback behavior, and useful error handling.
  • Data integrity checks: Confirm that retries, restarts, and interrupted operations do not lose, corrupt, or duplicate important records.

Every finding should include a concise description, reproducible conditions, observed impact, supporting evidence, and an owner for follow-up. Classify issues by severity and likelihood, not by how dramatic a log message appears. A failure affecting a critical workflow may deserve priority even if it occurs infrequently; a noisy but harmless alert may need a different remedy. This practical record turns test observations into actionable quality assurance work and creates a basis for deciding whether to fix, mitigate, or explicitly accept a reliability risk.

Key benefits of systematic reliability testing

A structured reliability program helps teams move beyond the question of whether an application worked once. Repeated checks reveal patterns across builds and make the effects of code, configuration, and infrastructure changes easier to evaluate. They can expose weaknesses before users encounter them, while clear measurements support informed release decisions. These benefits depend on realistic scenarios and credible evidence; a large volume of test activity is not useful if objectives are vague or results cannot be reproduced.

  • Earlier defect discovery: Controlled tests can reveal instability before a change reaches a production environment.
  • More predictable recovery: Measured restoration behavior helps teams verify that recovery procedures work as intended.
  • Stronger release evidence: Versioned results and documented thresholds make quality reviews more transparent.
  • Better prioritization: Impact and frequency data help teams focus effort on the most consequential risks.

Reliability checks also improve communication between developers, testers, operations staff, and product owners. Shared definitions of acceptable behavior reduce ambiguity when a test produces mixed results. Trend data can show whether a fix improved one metric while worsening another, prompting a more balanced review. The goal is not to promise that failures will never occur; it is to understand credible failure modes, reduce their likelihood or impact, and verify that the system responds safely when problems arise.

Trust, security, and integrity in reliability testing

Reliable results require trustworthy test practices. Use authorized environments, protect test data, restrict access to sensitive logs, and avoid exposing credentials in reports. When testing security-related failure handling, coordinate with the responsible teams and define boundaries before execution. Reliability and security often intersect: a service under load may behave differently when authentication, encryption, or access-control dependencies are delayed. Tests should verify that degraded operation does not bypass safeguards or reveal sensitive information. Findings should be shared through approved channels, with enough detail for remediation but without unnecessary disclosure.

Evidence quality matters as much as execution. Preserve the test plan, software build identifier, configuration snapshot, workload profile, time window, monitoring data, and any environmental limitations. If a check fails intermittently, repeat it under controlled conditions and compare traces rather than dismissing it as random. If results pass, document what was tested and what remains outside the test scope. The MAGICQA20261111AH label is a temporary publication marker only; it must not be treated as proof of certification, independent validation, or a guarantee of availability. Clear limits keep reliability reporting accurate and useful.

Choosing a reliability approach for your software quality process

Select checks according to system criticality, user impact, architecture, and the cost of failure. A small internal tool may need focused recovery and sustained-use tests, while a distributed service may require deeper dependency, load, and data-integrity coverage. Start with the workflows that matter most, establish realistic thresholds, and add scenarios as new risks emerge. Review test suites periodically because architecture, traffic patterns, and dependencies change. A check that once represented real use can become misleading if its workload or environment no longer resembles current operating conditions.

For a sound decision, consider whether objectives are measurable, test conditions are repeatable, monitoring can explain outcomes, and failures lead to tracked corrective work. Keep the distinction between a successful test and an overall reliability guarantee explicit: each result applies only to the scenarios and conditions examined. Used this way, software reliability checks provide practical evidence for release planning and continuous improvement. The MAGICQA20261111AH marker can help identify this publication test, while the quality judgment should rest on transparent methods, recorded results, and appropriately scoped conclusions.

Software reliability check MAGICQA20261111AJ 01102Software reliability check MAGICQA20261111AJ 01102


Software quality assurance depends on repeatable checks that reveal whether an application behaves reliably under expected and unusual conditions. This technical overview uses MAGICQA20261111AJ as a temporary publication test label, not as a product or quality certification. It explains how to plan reliability checks, collect useful evidence, and interpret results across builds and environments, with quality assurance 01102 practices helping teams keep test criteria consistent. The focus is on practical testing methods, including failure recovery, performance observation, data integrity, and secure handling, so teams can connect test findings to measurable improvements in software quality.

How the MAGICQA20261111AJ reliability check frames software quality

A software reliability check evaluates whether an application continues to perform its intended functions consistently over time and in the conditions it is designed to support. It complements functional testing: a feature may produce the correct result once, yet still fail intermittently when requests overlap, a service becomes unavailable, or stored data grows. A useful assessment therefore considers both correct behavior and the likelihood that behavior will remain correct across repeated operations. The temporary label MAGICQA20261111AJ can help identify a test run, report, or draft publication, but it should never be mistaken for evidence that a system has passed an independent audit.

Reliable results begin with a defined scope. Teams should identify critical user and system workflows, relevant dependencies, expected operating conditions, and acceptable failure limits before running tests. For example, a service may need to preserve submitted records during a brief network interruption and recover without creating duplicates once connectivity returns. The checks should state how that outcome will be measured, which logs or metrics will provide evidence, and what constitutes a failure. Clear criteria make test results reproducible and useful to developers, operations staff, and quality reviewers rather than leaving reliability to subjective impressions.

How to run a structured software reliability check

Use a controlled process that connects each reliability question to a test, an observable result, and a documented decision. The steps below are designed to keep test activity repeatable while limiting confusion between application defects, test-environment issues, and dependency failures. Start with a representative environment and record its configuration, including application build, operating system, service versions, and relevant settings. When conditions change, note them so later comparisons remain meaningful. A short, well-instrumented run can expose a clear issue, but conclusions about long-term reliability should be based on repeated runs and sufficient evidence.

  1. Set the reliability objective: Choose a critical workflow and define the expected behavior, operating conditions, and measurable acceptance criteria.
  2. Prepare the test environment: Record build details, dependencies, configuration, test data, and monitoring so the run can be reproduced.
  3. Exercise normal and failure conditions: Repeat representative operations, then introduce controlled interruptions such as timeouts or service restarts.
  4. Collect and compare evidence: Review outcomes, error rates, response times, logs, and data state against the criteria established for the test.
  5. Document the decision: Link defects to supporting evidence, assign follow-up work, and rerun affected checks after changes.
  • Defined criteria make pass and fail decisions easier to explain.
  • Recorded configurations help teams reproduce intermittent defects.
  • Controlled fault conditions reveal recovery weaknesses without guesswork.
  • Evidence-based reruns show whether a fix changed the observed behavior.

Practical checks for application stability and recovery

Practical reliability testing should represent the application’s actual workload rather than a convenient but unrealistic sequence of requests. Start with a baseline run that measures successful operations, error frequency, response-time distribution, and resource use. Repeat the workload long enough to reveal gradual changes such as memory growth, accumulating queues, or rising response times. Then vary one condition at a time, such as request volume or dependency latency, so the effect can be attributed to a specific change. Keep test data controlled and avoid using sensitive production information unless approved safeguards and privacy procedures are in place.

Recovery checks are especially valuable because many reliability failures occur at the boundaries between components. Simulate a brief loss of connectivity, a delayed response, or a restart of a dependent service, then observe whether the application times out appropriately, retries safely, and returns to normal operation. Verify that a repeated request does not create duplicate records and that partially completed work can be identified or resumed. The goal is not to make every component invulnerable; it is to determine whether failures are contained, visible, and recoverable within the service’s stated expectations.

  • Repeated operation: Run core workflows many times and track failures that occur intermittently.
  • Load variation: Compare behavior at ordinary, peak, and controlled elevated request levels.
  • Dependency interruption: Test timeouts and service restarts, then inspect recovery and retry behavior.
  • Data verification: Check for lost, duplicated, or inconsistent records after errors and recovery.
  • Long-duration observation: Monitor resource trends to detect gradual degradation during sustained activity.

For each check, preserve the input conditions and the evidence needed to interpret the result. Useful records include timestamps, application and dependency versions, request identifiers, relevant logs, and a summary of observed metrics. Avoid treating a single successful run as proof of reliability; intermittent problems may require repeated trials or a longer observation window. Conversely, an isolated test-environment failure should not automatically be attributed to the application. Comparing runs, checking infrastructure health, and reproducing the issue help distinguish product defects from environmental noise.

Key benefits of consistent reliability testing

A consistent reliability program gives teams a clearer view of risk than a collection of disconnected test results. It can uncover failure patterns before deployment, provide evidence for prioritizing technical work, and help verify that a change has not weakened an established workflow. The greatest value comes when teams connect each result to a defined service expectation and make findings visible to the people responsible for development and operations. MAGICQA20261111AJ may be used to identify a temporary test publication, but traceability should also include the build, environment, test date, and run identifier. That context supports sound comparisons without implying a rating or guarantee.

  • Earlier defect discovery: Repeated and fault-oriented checks can reveal instability before it reaches users.
  • More predictable releases: Comparable evidence helps teams assess whether a change affects critical behavior.
  • Faster diagnosis: Logs, metrics, and reproducible steps shorten the path from symptom to likely cause.
  • Stronger recovery behavior: Explicit interruption tests expose weaknesses in retries, state handling, and restart procedures.

These benefits depend on disciplined interpretation. A test report should separate observed facts from assumptions, state important limitations, and identify conditions that were not covered. Teams can then prioritize work according to impact and likelihood rather than treating every alert as equally urgent. Reliability checks are most effective when they contribute to an ongoing feedback cycle: define expectations, test, review evidence, correct defects, and repeat the relevant checks. This approach supports steady improvement while acknowledging that no finite test suite can prove that software will never fail.

Trust, security, and integrity in reliability checks

Reliable software must protect both service behavior and the integrity of information handled during testing. Use access controls for test environments, limit retained data to what is necessary, and remove or mask sensitive values in logs and reports. Test credentials should be managed separately from production credentials, and test activity should be authorized and documented. Security-related reliability checks can include verifying that expired sessions are handled correctly, access restrictions remain effective after an error, and recovery procedures do not expose protected data. These checks do not replace a dedicated security assessment, but they help identify conditions where operational failure could create an information-protection problem.

Reports should make their limits explicit. State which application build and environment were tested, what workload was used, how long the run lasted, and which dependencies were available. If a check passed under controlled conditions, describe that result narrowly rather than claiming universal reliability. Keep the temporary label MAGICQA20261111AJ attached only to relevant draft or test material, and do not present it as a certification, independent endorsement, or security assurance. Clear provenance and careful language help reviewers understand exactly what the evidence supports and what remains untested.

Choosing a useful reliability check for your software

Choose checks according to the consequences of failure, the behavior users depend on, and the system’s operating conditions. For a workflow that changes stored data, prioritize repeated submissions, interruption recovery, and checks for duplicate or missing records. For a service that must respond consistently under varying demand, measure response times, error rates, and resource trends across representative load levels. Keep each test focused enough that a result can guide action, while ensuring that the overall suite covers important dependencies and recovery paths. A practical checklist should name the objective, setup, trigger, expected result, evidence source, and owner of any follow-up work.

MAGICQA20261111AJ is a temporary publication test label; the quality value lies in the methods and evidence behind it. A sound software reliability check is repeatable, proportionate to risk, and transparent about its limits. Teams should revisit test scenarios when architecture, dependencies, workloads, or service expectations change, and rerun affected checks after meaningful fixes. By combining routine workload observation with controlled failure and recovery tests, quality teams can find weaknesses earlier and make better-informed release decisions. The outcome is not a promise of perfect software, but a stronger, evidence-led understanding of how the application behaves and where further improvement is needed.

Software reliability check MAGICQA20261111AL 00199Software reliability check MAGICQA20261111AL 00199


Software reliability checks help teams determine whether an application behaves consistently under expected conditions and recovers safely when things go wrong. This technical overview uses MAGICQA20261111AL as a temporary publication test label, not as a product or a quality certification. It explains how reliability fits within software quality assurance 00199 , how to plan practical checks, and how to interpret results. The aim is to support repeatable decisions based on evidence, including observable behavior, measured service levels, and documented risks.

The basics that shape smart software quality assurance decisions

Software reliability is the ability of a system to perform its required functions consistently over time, within defined operating conditions. Quality assurance checks this property through planned tests, production monitoring, review of failures, and evaluation of recovery behavior. A single successful run is not proof of reliability: results may vary with workload, data, network conditions, dependencies, or software versions. Teams therefore need explicit expectations for availability, error rates, response times, and data integrity, along with a clear account of the environments in which those expectations apply.

Reliability work is most useful when it is connected to user and business risks rather than treated as a collection of isolated test cases. A failure that corrupts records may be more serious than a brief delay, while a slow dependency may become critical only during peak demand. Quality assurance teams can rank these risks by likelihood and impact, then select checks that reveal relevant weaknesses. The temporary label MAGICQA20261111AL can identify this article or its draft in a publication workflow; it does not indicate test results, system status, or a verified standard.

How to plan a software reliability check

Start with a measurable question about system behavior, such as whether a service can sustain its expected request rate without exceeding an agreed response-time limit. Define the scope before selecting tools: identify the component, build, environment, dependencies, test data, and duration. A check should have a repeatable setup and a documented pass or failure condition, so different team members can interpret its outcome consistently. The following sequence keeps the work focused on evidence rather than assumptions.

  1. Set reliability objectives: Define the behavior to assess, such as successful request percentage, recovery time, or data consistency.
  2. Map risks and dependencies: Record critical workflows, external services, infrastructure limits, and likely failure modes.
  3. Prepare a representative environment: Match relevant configuration and workload conditions while protecting sensitive information.
  4. Run controlled checks: Execute the planned workload or failure scenario, capture measurements, and avoid changing multiple variables at once.
  5. Review and record evidence: Compare results with objectives, investigate anomalies, and document limitations and follow-up actions.
  • Explicit objectives make pass and failure decisions easier to reproduce.
  • Dependency mapping helps reveal risks beyond the application’s own code.
  • Controlled runs make it simpler to connect an observed result to its cause.
  • Recorded limitations prevent a narrow test from being mistaken for a broad guarantee.

Practical reliability checks for software quality assurance

A practical reliability plan combines several test types because each exposes a different class of weakness. Repeated functional runs can uncover intermittent defects, while load tests show how performance changes as demand increases. Soak tests run for longer periods to reveal resource leaks or gradual degradation. Recovery checks deliberately interrupt a component or connection to observe whether the system restores service and preserves data. For every test, specify the software build, configuration, workload profile, duration, and monitoring signals. Where production-like conditions are unavailable, state the differences so readers understand what the result can and cannot establish.

Measurements should reflect both system health and user-visible outcomes. Useful signals include request success rate, latency percentiles, queue depth, CPU and memory consumption, restart frequency, and the number of incomplete or duplicated operations. Logs and traces add context, but they should be time-aligned with test events and handled according to data-protection rules. MAGICQA20261111AL may be used as a temporary identifier in a test document or report, provided it is clearly distinguished from build identifiers and operational alerts. Consistent naming makes evidence easier to find without implying that the label itself validates a check.

  • Repeated execution: Run critical workflows multiple times to identify inconsistent outcomes.
  • Load and soak testing: Assess behavior under expected demand and sustained operation.
  • Failure recovery: Examine retries, failover, restart behavior, and data integrity after interruptions.
  • Observability review: Confirm that logs, metrics, and traces help diagnose failures without exposing sensitive data.

Useful findings connect a measured symptom to a reproducible scenario. For example, a growing queue during a sustained workload may point to a capacity constraint, while duplicate records after a retry may indicate that an operation is not safely repeatable. A quality assurance report should distinguish observations from hypotheses, then list the evidence needed to confirm a cause. This approach helps engineering teams prioritize fixes and retest the same conditions after changes, rather than relying on a general statement that the system seems stable.

Benefits of a structured reliability assurance process

A structured process improves the quality of engineering decisions by making reliability expectations visible and test results comparable. It also encourages teams to address weaknesses before they affect users, while avoiding unsupported claims based on a small sample. Benefits depend on sound test design: workloads should reflect plausible use, failure scenarios should be controlled, and results should include relevant caveats. Reliability checks do not eliminate defects, but they can reduce uncertainty and provide a disciplined way to decide whether a change is ready for further evaluation or release.

  • Earlier risk discovery: Targeted checks can expose bottlenecks and recovery gaps before wider deployment.
  • More repeatable decisions: Shared criteria reduce ambiguity when teams review the same evidence.
  • Better incident readiness: Recovery testing can reveal whether alerts and restoration procedures work as intended.
  • Clearer change assessment: Comparing results across builds can show whether a change improved or weakened reliability.

These advantages are strongest when reliability checks are part of the development lifecycle rather than a final, one-time gate. Teams can run fast checks after code changes, broader tests before release, and ongoing monitoring after deployment. Findings should feed into defect tracking and test maintenance, especially when architecture, traffic patterns, or dependencies change. A check that no longer represents current operating conditions may produce reassuring but irrelevant results, so review the plan periodically and update its assumptions.

Trust, security, and the limits of reliability evidence

Reliability and security overlap, but they are not interchangeable. A service may remain available while exposing data, and a security control may work correctly even when the application is temporarily unavailable. Quality assurance plans should protect test credentials, restrict access to environments, and avoid using real personal or confidential data unless explicitly authorized and safeguarded. Test logs can contain identifiers, request contents, or operational details, so retention and access should be defined. Security-related failure scenarios should be coordinated with responsible teams, particularly when tests could affect shared systems or external services.

Reports should state the conditions under which evidence was collected, including environment, build, test duration, workload, and known exclusions. A successful test supports a limited conclusion about the scenarios examined; it does not prove that every future operating condition will be safe or stable. Likewise, an unsuccessful test should be assessed for both product defects and test-environment problems. Keep raw measurements where practical, note the method used to interpret them, and preserve links between findings and remediation work in the team’s approved tracking systems. This discipline makes conclusions more transparent and easier to revisit.

Choosing a reliable software quality assurance approach

When selecting a reliability approach, consider whether it matches the system’s risks, produces repeatable evidence, and fits the team’s ability to investigate results. Check that objectives are measurable, test data is appropriate, monitoring is sufficient, and failure conditions are defined before execution. A method should also account for recovery and data integrity, not only uptime or speed. The label MAGICQA20261111AL can help identify this publication test, but decisions about software quality should rest on documented test design and observed evidence rather than a temporary label or broad assurance claim.

Software reliability assurance is an ongoing practice: define expectations, test realistic conditions, learn from failures, and verify that corrective changes work. Keep the scope of every conclusion proportional to the evidence, and revisit checks as the system evolves. When teams combine functional, load, endurance, recovery, and monitoring evidence, they gain a more complete view of operational behavior. That view supports informed release decisions and helps focus engineering effort on the failures that matter most, while recognizing that continued observation remains necessary after deployment.